Free Data Engineer Resume Template & Examples
A good data engineer resume proves that data arrives on time, in the right shape and at a cost the business can live with. Hiring managers scan for your stack (SQL, Python, Spark, Airflow, a cloud warehouse), the volume you handle and what your pipelines made possible for the people downstream. This page covers format, certifications by country, summary and bullet examples, keywords and the mistakes that sink strong candidates. Upload your current resume as a PDF, Word file or photo, and ResumeInk rebuilds it in an ATS-readable design you can edit line by line.
Best resume format for a data engineer
Use reverse-chronological order. One page is right for graduates and engineers with under five years of experience; two pages are fine once you have led platform work, migrations or a team. In the UK, India and Australia a two-page CV is normal at mid level, as long as page two still earns its place.
A reliable order: header with GitHub and LinkedIn, a three-line summary, grouped skills, experience, selected projects, education, then certifications. If you are moving across from analytics or software, put projects above experience so the reader sees pipeline work first.
Layout tip: ResumeInk's Skills-first layout puts a shaded block of grouped skills before your experience, which suits a stack-heavy role. The Developer stack layout keeps tools and projects prominent and pairs with the Terminal developer theme if you like a monospace look; the developer resume template explains the style. Both read cleanly in applicant tracking systems, and you can switch between them without retyping.
What to include in a data engineer resume
- Header: contact details, LinkedIn and a GitHub link, but only if the repositories show real pipeline code, tests and a readable README.
- Summary: your core stack, the scale you work at (rows, events or terabytes a day) and one business result.
- Skills, grouped: languages, batch and streaming processing, orchestration, warehouses and lakehouses, cloud, data quality and modelling.
- Experience: for each role, what you built or migrated, the volume, the freshness or reliability you achieved, and the cost or time you saved.
- Projects: an end-to-end pipeline with ingestion, transformation, tests and a dashboard or API at the end. Essential for freshers and for anyone moving over from data analyst roles.
- Education: degree, institution and year. A B.Tech, BSc or MCA in computer science is common, but strong work can outweigh the degree.
- Certifications: cloud or platform certifications with the year earned.
If your work leans towards training and serving models, the machine learning engineer resume page may fit you better.
Data engineer certifications and credentials by country
No country licenses data engineers. Employers look at what you have shipped, the platforms you know and, often, a vendor certification that matches their stack. The ones recruiters recognise:
- Cloud: Google Cloud Professional Data Engineer, AWS Certified Data Engineer — Associate, and Microsoft Certified: Fabric Data Engineer Associate (exam DP-700), which replaced the retired Azure Data Engineer Associate (DP-203).
- Platforms: Databricks Certified Data Engineer Associate or Professional, SnowPro Core and SnowPro Advanced: Data Engineer, and the Confluent Certified Developer for Apache Kafka.
India: many job ads, especially from IT services firms, name a cloud certification as preferred, so list yours near the top. US: experience and system design count most; a certification helps when you are changing stacks. UK: government and defence data work may need SC or DV clearance, so state an active clearance by level. Australia: state your working rights, and any Baseline or NV1 clearance for government roles. Everywhere, a line on the data protection law you worked under (GDPR or UK GDPR, India's DPDP Act, HIPAA for US health data) helps when you have handled personal data.
Data engineer resume summary examples
Three lines: stack, scale, result. Adapt these:
- Entry level: Computer science graduate who built a streaming project that moves 2 million simulated card transactions a day through Kafka and Spark into PostgreSQL, with dbt tests and an Airflow schedule. Comfortable with SQL window functions, Python and Docker, and looking for a first data engineering role.
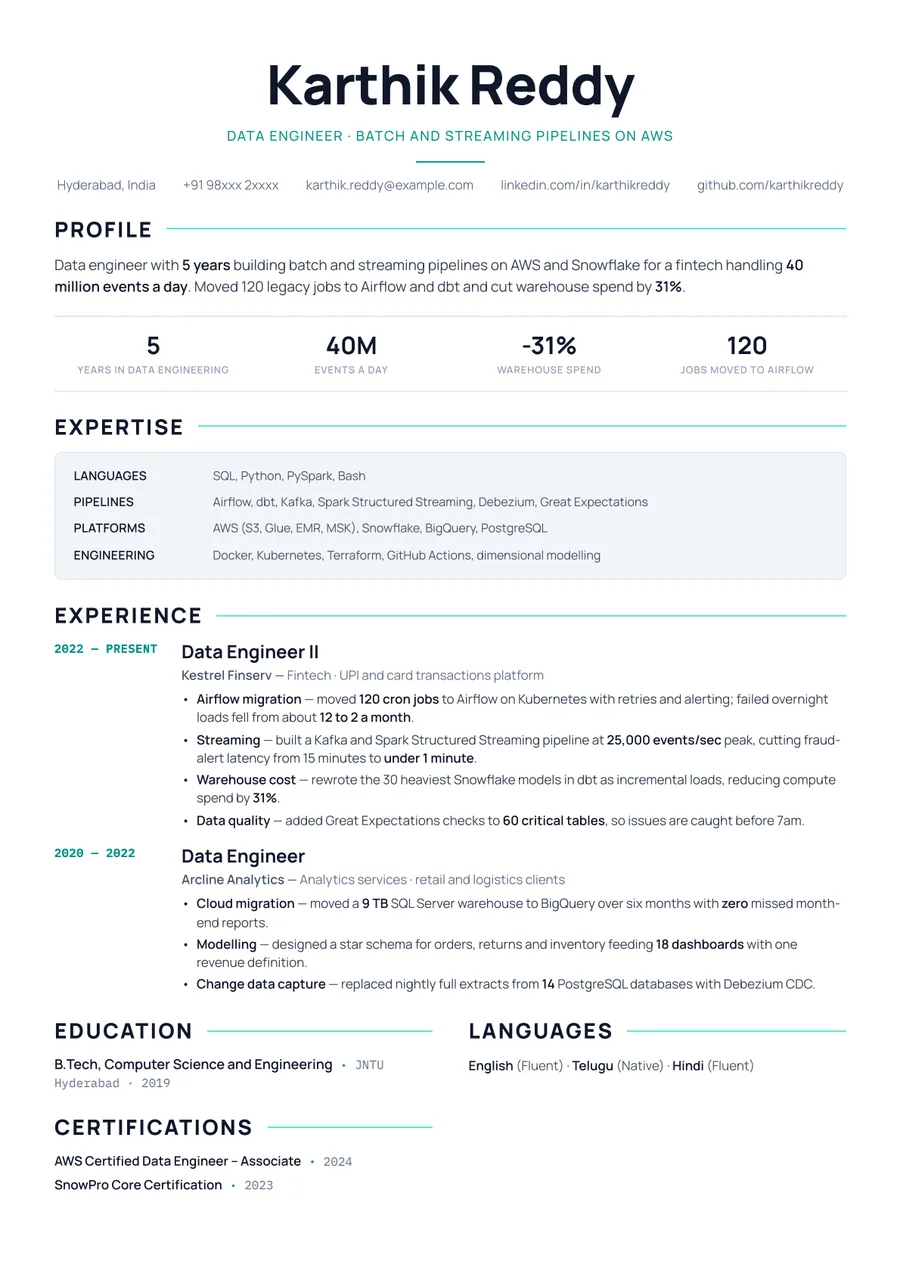
- Mid level: Data engineer with five years building batch and streaming pipelines on AWS and Snowflake for a fintech processing 40 million events a day. Moved 120 legacy jobs to Airflow and dbt, cut warehouse spend by 31% and brought dashboard freshness from daily to hourly.
- Senior: Lead data engineer with 11 years in retail and logistics, running a team of seven on a Databricks lakehouse used by 300 analysts. Introduced data contracts and quality checks that cut broken-report incidents by two thirds, and owns the platform roadmap with the head of analytics.
Data engineer resume bullet point examples
Lead with the verb, give the volume, end with the effect on the people who use the data:
- Migrated 120 cron-scheduled Python jobs to Airflow on Kubernetes with retries and alerting; failed overnight loads dropped from about 12 a month to 2.
- Built a Kafka and Spark Structured Streaming pipeline handling 25,000 events per second at peak, cutting fraud-alert latency from 15 minutes to under one minute.
- Rewrote the 30 heaviest Snowflake models in dbt as incremental loads with clustering, reducing monthly compute spend by 31%.
- Designed a dimensional model for orders, returns and inventory that feeds 18 dashboards, replacing four conflicting revenue definitions with one.
- Added Great Expectations checks to 60 critical tables, so data issues are caught before 7am instead of being reported by finance mid-morning.
- Moved a 9 TB on-premise SQL Server warehouse to BigQuery over six months with zero missed month-end reports.
- Replaced nightly full extracts from 14 PostgreSQL databases with Debezium change data capture, taking five hours of load off the source systems each night.
- Mentored three junior engineers and introduced code review and CI for SQL, halving production hotfixes within two quarters.
Skills & ATS keywords for data engineer resumes
Mirror the exact tool names in the job ad, and list only what you could discuss in an interview. Terms that recur in data engineering ads:
- Languages: SQL, Python, Scala, Java, Bash.
- Processing and orchestration: Apache Spark, PySpark, Kafka, Flink, Airflow, Dagster, dbt, ETL and ELT, batch and streaming, change data capture.
- Storage: Snowflake, BigQuery, Redshift, Databricks, Delta Lake, Apache Iceberg, PostgreSQL, data lakes and lakehouses.
- Cloud and DevOps: AWS (S3, Glue, EMR, Kinesis), Azure Data Factory, Google Cloud Dataflow, Docker, Kubernetes, Terraform, CI/CD, Git.
- Practices: data modelling, star schema, data quality, data governance, observability, data contracts, cost optimisation.
- Soft skills: working with analysts and product teams, clear documentation, on-call ownership, prioritising requests.
ResumeInk's AI can tailor your skills to a pasted job description; the guide to resume keywords for ATS screening explains how to choose them, and the ATS resume checker shows how readable the result is.
Common data engineer resume mistakes
- A wall of logos. Forty tools in a list says little. Group them, and make sure each important one appears in a bullet that shows what you did with it.
- No sense of scale. Built ETL pipelines fits any job. Add rows, events, tables, terabytes or the number of sources.
- Missing the downstream result. Pipelines exist for someone. Say who used the data and what became faster, cheaper or more trusted.
- Hiding reliability work. Tests, alerting, backfills and on-call duty are what senior hiring managers look for. Give them a bullet.
- Confidential detail. Leave out internal table names, clients under NDA and anything that reveals schema or security setup.
- Stretching a title. If a role was mostly dashboards, say so and lead with your pipeline projects; the guide to a career change resume shows how to frame the move.
Premium, ATS-friendly templates


Build your resume in minutes
Upload your current resume, edit anything, then preview and download it free.
Upload your resumeFrequently asked questions
How do I write a data engineer resume with no experience?
Build one or two end-to-end projects that ingest real or public data, transform it with SQL or Spark, test it and schedule it, then put them above your education with the volume and tools named. Add internships, coursework and any job where you wrote SQL or automated a report.
Which certification is best for a data engineer resume?
The one that matches the stack in the jobs you want: Google Cloud Professional Data Engineer, AWS Certified Data Engineer Associate, Microsoft Fabric Data Engineer Associate, or a Databricks or Snowflake certification. It supports your experience but does not replace pipeline work you can talk through.
Should a data engineer resume be one or two pages?
One page until you have about five years of experience, then two pages if the extra space holds migrations, platform design or leadership. Cut older roles to two lines each before you shrink the font.
How do I move from data analyst to data engineer on my resume?
Lead with engineering evidence: pipelines you automated, SQL models you maintained, Python scripts that replaced manual work and a project with orchestration and tests. Keep your analyst job title accurate, but write the bullets around the engineering parts of the job.
Should I put my GitHub on a data engineer resume?
Yes, if it holds work you are happy for an engineer to read, ideally a pipeline with tests, a clear README and a diagram. Pin your best two repositories, and leave the link off if the profile only has course exercises.